What should you back up on a Linux server?
Learn what to back up on a Linux server: application data, databases, configuration, Docker volumes, recovery keys, and the evidence needed to restore safely.
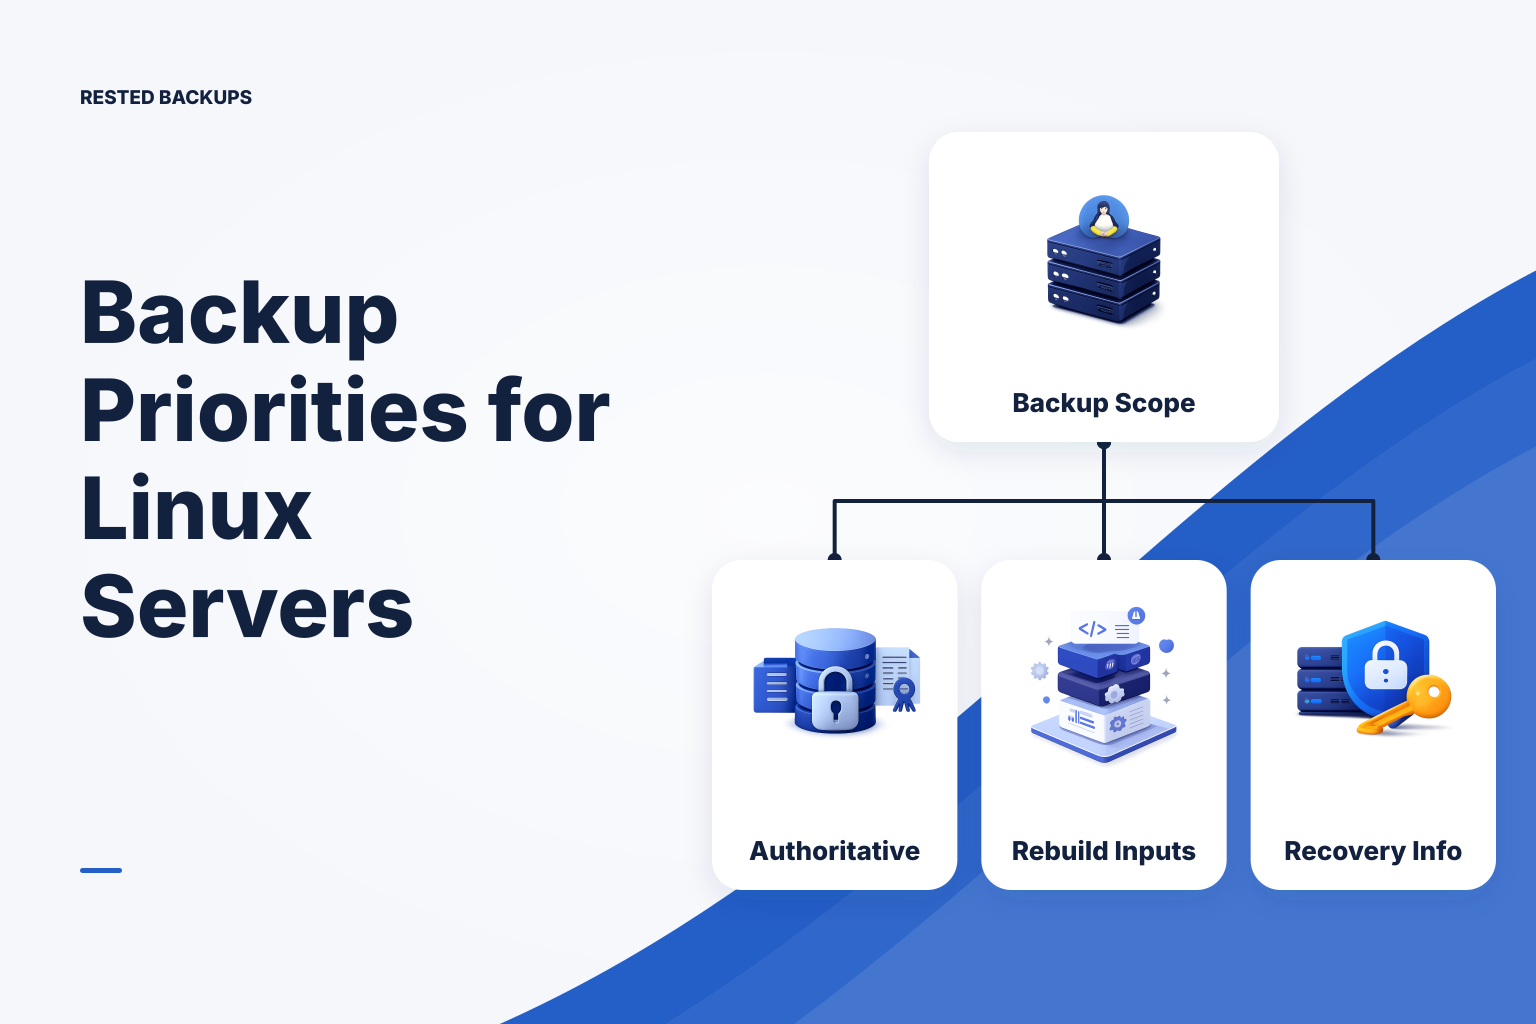
Back up the state you cannot safely recreate
Back up the data, configuration, credentials, and recovery metadata needed to rebuild the service—not automatically every byte on the server. The safest starting point is a replacement-server exercise: if this machine vanished now, what would be impossible, slow, or risky to recreate?
Operating-system packages can usually be installed again. Container images may be pulled again, and version control may provide application code and infrastructure definitions. Customer uploads, database records, locally generated keys, unpushed changes, and server-only configuration are different. If the host holds the only copy, losing it may be permanent.
Classify each item by its replacement source and recovery cost, not by its directory size. A small configuration file can delay recovery longer than a large cache if nobody knows its required values. This is also why a green backup job is not enough: it confirms that assigned work completed, not that the assigned scope can rebuild the service. See [why a successful backup can still be unrecoverable](/blog/successful-backup-still-unrecoverable) for the distinction.
- **Authoritative state:** the copy you must preserve, such as database records, uploads, certificates, and business documents.
- **Rebuild inputs:** code, infrastructure definitions, package lists, image tags, and installation instructions that recreate the host.
- **Recovery dependencies:** storage location, repository access method, encryption or recovery key ownership, required secrets, and restore order.
- **Transient state:** runtime interfaces, caches, temporary files, and derived artifacts that have a documented, tested reconstruction path.
Define the recovery event before choosing paths
The backup scope for a deleted file is not necessarily the scope for a lost server or compromised provider account. Write down the recovery events you intend to handle, then decide what recovery point and recovery time are acceptable for each service. Your recovery point objective (RPO) is the maximum data loss measured in time; your recovery time objective (RTO) is the time available to return the service to use.
A provider snapshot can help rebuild a whole machine quickly, but it does not replace database-aware backups or an independent copy when the provider account, snapshot policy, or disk state is part of the failure. Conversely, a logical database dump may be excellent for recovering records but not sufficient to rebuild application uploads and host configuration. Use layers where the recovery scenario requires them.
- Accidental deletion: retain useful snapshots and practice restoring a file, folder, or database object to a safe target.
- Lost or failed server: preserve application state, database artifacts, configuration, deployment inputs, and a documented rebuild sequence.
- Storage or account compromise: consider an independently controlled copy and review storage permissions, retention, and any immutability design carefully.
- Database corruption: use a database-native backup method that matches the point in time and consistency you need.
Protect system and service configuration
On an FHS-style Linux system, /etc is the main home for host-specific system configuration. It can contain network settings, service units, scheduled jobs, user and group information, web-server configuration, database access rules, and references to secrets. A recoverable copy gives you evidence of how the host was assembled.
Do not assume every important setting is under /etc. Locally installed software may use /opt, /usr/local, /srv, an application directory, or a service user’s home. Review custom systemd units, environment files, reverse-proxy configuration, firewall rules, deployment scripts, and the actual configuration path passed to each service.
Configuration backups are sensitive. They may include password hashes, private keys, API credentials, internal hostnames, or database connection details. Encrypt backup data, restrict repository access, and decide which secrets should instead be restored from a dedicated secret manager. Do not treat a broad copy of /etc as permission to distribute its contents widely.
- Include service definitions, timers or cron jobs, reverse-proxy configuration, firewall configuration, and application environment-file locations.
- Record package repositories, enabled services, image tags, and custom installation steps so a replacement host can be reproduced.
- Keep secrets under an explicit ownership plan: identify where the authoritative secret copy lives, who can access it during an incident, and how it is supplied to the restored service.
Find application data where the service actually writes it
Application data commonly lives under /srv, /var/lib, /var/www, /opt, or a purpose-built mount such as /data. These are conventions, not proof. Find the authoritative location from service configuration, application settings, mount tables, and runtime container configuration.
Include user-generated uploads, application-managed documents, media, license files, generated reports, local queues whose loss matters, and indexes that cannot be reliably rebuilt. Mark caches and derived assets separately. If an item can be recreated cheaply and reliably from preserved source data, excluding it can reduce backup time, storage use, and restore clutter.
Check separate disks and network mounts. Linux presents them in one directory tree, so an ordinary-looking path may be on a filesystem that was absent when the backup ran. A network mount may also already be protected by another system; backing it up again can add cost or introduce consistency problems. Record the chosen owner and recovery method rather than guessing later.
- Inspect service configuration for data directories, upload paths, attachment stores, spool directories, and external filesystem references.
- Review mounted filesystems before and after deployments; a new mount can silently move authoritative data outside an existing backup path.
- For every included path, name the service it supports and the validation you will perform after restore.
Back up databases with database-aware methods
A running database is not merely a directory of unrelated files. The engine coordinates memory, transaction state, data files, and logs. Use its supported logical dump, physical backup, or documented snapshot procedure rather than assuming that a generic file copy during writes is recoverable.
For PostgreSQL, pg_dump creates a consistent logical backup of one database while users continue working. Cluster-wide roles and other global objects need separate consideration, and point-in-time recovery uses a different design involving base backups and write-ahead logs. Choose the method from the required scope, database size, RPO, and restore-time target; the [PostgreSQL backup and restore documentation](https://www.postgresql.org/docs/current/backup.html) describes the supported approaches.
Protect the resulting backup artifacts off-host and test them with the matching restore tool. A recent, large dump proves little by itself. In an isolated target, verify that the restore completes, required roles and extensions exist, representative records are present, and the application can connect. For a deeper PostgreSQL scope decision, compare [pg_dump and pg_dumpall](/blog/pg-dump-vs-pg-dumpall).
- Logical backup: portable and useful for selected databases or objects, but restore time can be material for large datasets.
- Physical backup: can suit larger databases and point-in-time designs, but requires engine-specific procedures and recovery testing.
- Storage snapshot: may be useful only when it is coordinated with the database or when the documented crash-consistency and recovery process meets your requirement.
- Never rely on a live copy of a database volume as your only database recovery method unless the database vendor documents that exact procedure for your use case.
Include human work and administrative state
Home directories can contain scripts, SSH configuration, deployment notes, cron definitions, local repositories, and operational tools. Review the root user’s home as well as service and administrator accounts. Do not back up every personal cache by reflex, but do not assume all server administration is already captured elsewhere.
Ask operators what they would search for after losing the machine. A one-off migration script, manually maintained allowlist, local certificate, or unpushed configuration change can be operationally critical even when it should eventually move into version control. Backing it up helps recovery now; moving it to a reviewed system of record prevents the same hidden dependency later.
Keep an inventory of installed packages and enabled services when it will speed reconstruction. Package binaries are often replaceable, while the knowledge of which versions, repositories, and manual steps were used may not be. Treat the inventory as supporting recovery metadata, not as a substitute for application data.
- Review
/root, relevant user homes, service-account homes, and directories containing locally maintained scripts or certificates. - Move durable operational knowledge into version control, a documentation system, or a secret manager where practical.
- Document dependencies that are not on the host: DNS, email delivery, identity providers, container registries, license services, and third-party object storage.
Technical basis
First-party references
Technical claims and limitations in this guide were checked against these primary sources. Confirm version-specific behavior when designing a production recovery process.
Related from Rested
Common questions
Frequently asked questions
Should I back up the entire Linux root filesystem?
A full image can help with rapid machine recovery, but it should not replace an inventory of authoritative data and database-aware backups. Whole-filesystem copies include transient state and may still be inconsistent for live databases. If you use an image or snapshot, pair it with tested application and database recovery steps.
Which Linux directories are usually important to back up?
Common candidates include /etc, relevant user homes, /srv, the relevant parts of /var/lib, /opt, /usr/local, application-specific data directories, and separate data mounts. Confirm actual service configuration and mount points rather than relying on a universal path list.
Should I back up Docker volumes?
Back up the persistent state represented by named volumes and bind mounts, but use database-aware backups for live database data. A Compose file helps identify intended storage; runtime inspection is needed to confirm the mounts actually attached to running containers.
Do I need to back up /var/log?
Back up logs only when they serve a defined recovery, audit, security, or legal purpose. Many teams ship logs to a separate system instead. Set retention and access deliberately because logs can contain sensitive information and are not always required to restore an application.
Should package files be included in server backups?
Packages can usually be reinstalled from repositories or container images. Preserve the package and repository inventory, custom locally installed software, image references, and configuration needed to reproduce the host. Test that the required upstream sources remain available.